

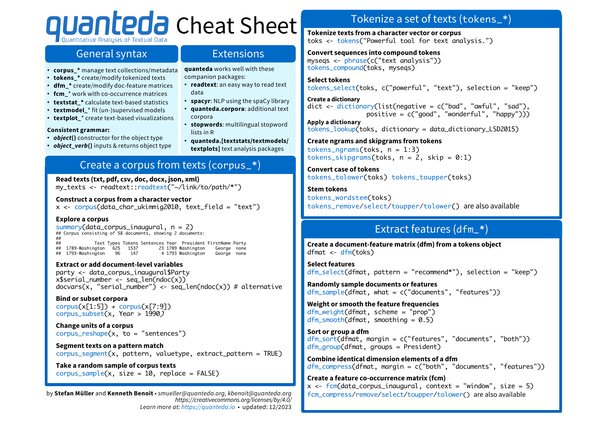
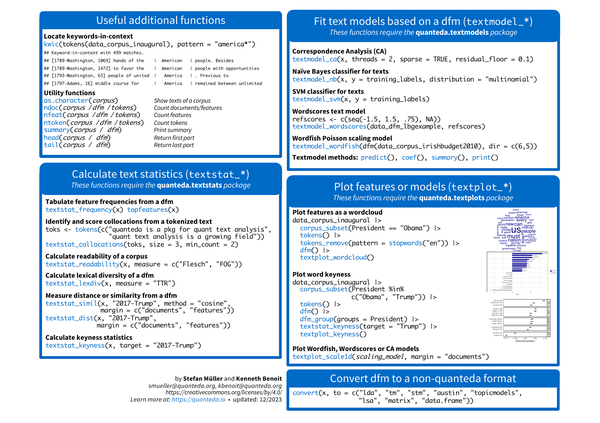
The quanteda package provides a framework for quantitative text analysis in R. Its consistent grammar uses corpus_* functions for text management, tokens_* for tokenization, dfm_* for document-feature matrices, textstat_* for statistics, textmodel_* for supervised and unsupervised models, and textplot_* for visualization.
What’s covered#
- General syntax – object-specific prefixes and companion packages (readtext, spacyr, stopwords)
- Create a corpus –
corpus(),corpus_subset(),corpus_reshape(),corpus_segment(),docvars() - Tokenize texts –
tokens(),tokens_compound(),tokens_ngrams(),tokens_skipgrams(),tokens_lookup()with dictionaries - Extract features –
dfm(),dfm_select(),dfm_weight(),dfm_group(),dfm_compress(),fcm() - Text statistics –
textstat_frequency(),textstat_collocations(),textstat_readability(),kwic() - Text models –
textmodel_nb()(Naïve Bayes),textmodel_svm(),textmodel_wordscores(),textmodel_wordfish() - Visualizations –
textplot_wordcloud()and othertextplot_*functions